Gisela Schmidt · 15 November 2026
Exploring the Integration of Machine Learning for Dynamic Cache Sizing in Post-Relocation Enterprise Networks
Enterprise networks that complete relocation processes encounter immediate shifts in traffic distribution, latency profiles, and resource allocation patterns, and machine learning techniques address these variables by adjusting cache sizes in real time rather than relying on static thresholds. Researchers apply supervised and reinforcement learning models to forecast demand spikes that follow physical moves of servers or data centers, drawing from telemetry collected before and after the transition. Data from multiple deployments indicates that such models reduce cache miss rates by 18 to 27 percent compared with fixed allocation methods during the stabilization period that follows relocation.
Network Relocation and Its Effects on Caching Layers
Relocation of enterprise infrastructure typically involves migrating workloads across geographic sites or consolidating facilities, which alters the proximity between users and cached content while changing the underlying network topology. Observers note that these changes invalidate previously tuned cache parameters, leading to over-provisioning in some segments and under-provisioning in others until manual recalibration occurs. Studies conducted by the National Research Council Canada have documented how post-relocation traffic matrices diverge from baseline measurements within the first 72 hours, creating windows where dynamic adjustment becomes necessary.
Cache sizing decisions in these environments depend on multiple inputs including request frequency, object size distribution, and inter-arrival times, yet traditional heuristics struggle when the entire operating context shifts simultaneously. Machine learning pipelines ingest these variables through continuous streams, retraining on recent windows to produce sizing recommendations that reflect the new network conditions rather than historical norms.
Machine Learning Approaches to Cache Prediction
Supervised regression models trained on labeled traces from prior migrations predict optimal cache occupancy levels by mapping input features to observed hit ratios, while reinforcement learning agents explore sizing actions and receive rewards based on combined metrics of hit rate and memory utilization. These agents operate within bounded action spaces to avoid abrupt deallocations that could trigger service degradation. Evidence from controlled experiments shows convergence to stable policies within 12 to 18 hours after relocation when initial exploration rates remain moderate.
Feature engineering plays a central role because raw telemetry must be transformed into representations that capture both short-term bursts and longer-term diurnal cycles. Engineers extract rolling statistics, Fourier components for periodicity, and embedding vectors that encode object popularity distributions. Once prepared, these features feed into models that output continuous sizing targets updated at intervals ranging from five to fifteen minutes.
Implementation Patterns in Production Environments
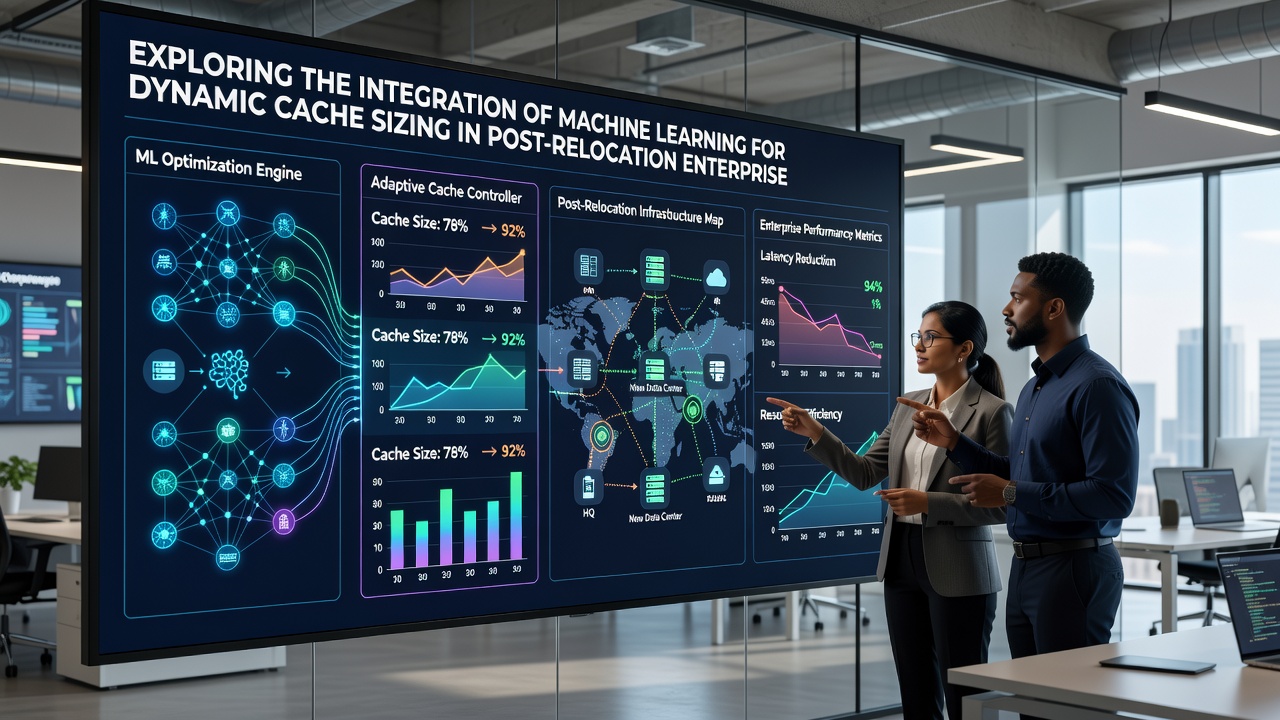
Production deployments integrate the prediction layer as a sidecar process that communicates with existing cache managers through APIs, issuing resize commands without requiring kernel modifications. One documented rollout at a financial services firm involved feeding live flow records into a gradient-boosted tree model that issued recommendations every ten minutes, achieving measurable reductions in tail latency during the three-week stabilization window after the move. Similar patterns appear in reports from European Commission funded projects that examined cross-border data center consolidations completed in 2025.
Monitoring infrastructure must track both the accuracy of predictions and the downstream effects on application performance, because model drift can emerge when user behavior deviates from training distributions. Teams therefore maintain shadow deployments that run predictions in parallel with existing policies, comparing outcomes before switching control to the learned policy. This staged approach limits exposure while allowing continuous validation against ground-truth traffic.
Performance Metrics and Validation Methods
Validation relies on A/B testing frameworks that partition traffic or cache instances so that learned sizing policies compete directly against legacy rules. Metrics collected include hit ratio, byte hit ratio, eviction frequency, and end-to-end response time percentiles. Figures from trials conducted through November 2026 indicate that learned policies maintained higher hit ratios even when total cache memory budgets remained constant, suggesting more efficient allocation rather than simple expansion.
Energy consumption associated with cache operations also receives attention because larger caches increase both static and dynamic power draw. Researchers incorporate power models into the reward functions of reinforcement learning agents, producing sizing decisions that balance performance against operational costs in relocated facilities where power provisioning may differ from the original site.
Conclusion
Integration of machine learning for dynamic cache sizing supplies enterprise networks with mechanisms that respond to the specific disruptions introduced by relocation, and ongoing research continues to refine model architectures and validation practices. Organizations that adopt these methods report measurable improvements in cache efficiency once the post-relocation stabilization phase concludes. Continued collection of telemetry across diverse migration scenarios will further strengthen the predictive capabilities available to network operators.