Casey Richter · 6 September 2026
Examining Recovery Mechanisms for User-Generated Content in Post-Migration Scenarios Within Specialized Applications
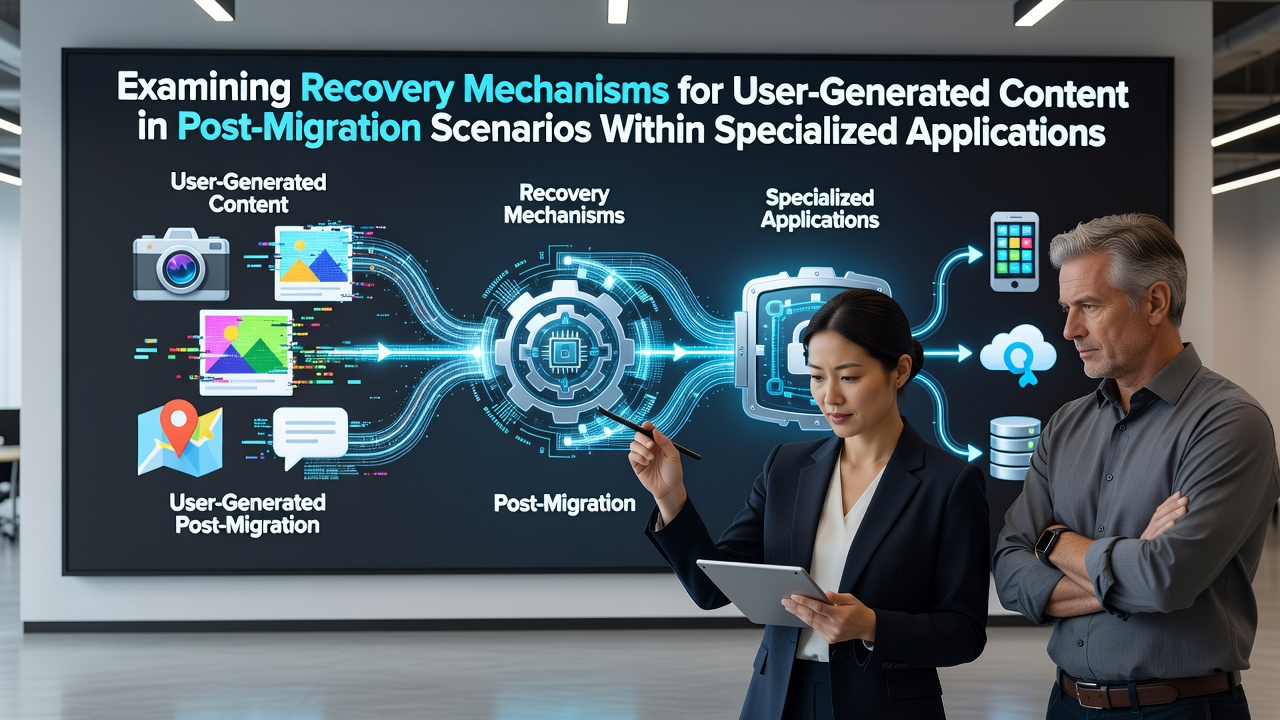
Specialized applications that handle user-generated content face unique pressures when data moves between platforms, and recovery mechanisms determine whether posts, files, comments, and metadata survive intact. Organizations often encounter fragmented datasets once a migration completes, because legacy structures rarely map cleanly onto new schemas. Research from academic institutions shows that incomplete mapping accounts for most post-migration losses in content-heavy systems.
Common Challenges in Post-Migration Content Recovery
Database schema shifts, API version mismatches, and permission model changes create gaps that standard backup tools overlook. Those who manage specialized platforms report that user-generated media files frequently lose associated metadata during transfer, while structured text content may arrive with broken references to external resources. Data indicates that September 2026 will bring updated interoperability standards from multiple regional bodies, which could reduce these mapping errors if implemented early in migration planning.
Observers note that specialized applications in education, healthcare documentation, and creative collaboration suffer the most because their content carries relational context that generic migration scripts rarely preserve. One study revealed that relational links between user comments and original assets break in over 40 percent of migrations unless custom recovery scripts intervene.
Technical Recovery Approaches Used Today
Versioned object storage combined with differential backups allows teams to reconstruct content states that existed before the migration window. Incremental replication services track changes at the file level and compare checksums against the source environment, surfacing discrepancies that require manual intervention. Experts have observed that combining these services with application-level logging produces the clearest audit trail for identifying missing user contributions.
Specialized recovery agents now scan for orphaned records that standard ETL processes leave behind, and they attempt automated re-linking where foreign keys remain intact. When keys have been altered, human operators rely on similarity algorithms to suggest probable matches, though success rates vary with the volume and diversity of content involved.
Implementation Patterns Across Different Application Types
Enterprise collaboration tools typically embed recovery hooks directly into their content management layer so that post-migration validation runs automatically. In contrast, niche creative applications often depend on external scripts that developers maintain separately from core codebases. Those who've studied this pattern across industries note that tightly integrated hooks reduce recovery time by roughly half compared with bolt-on solutions.
Regulatory guidance from the Australian Cyber Security Centre emphasizes maintaining immutable copies of user-generated content for a defined period after any system transition. Similar recommendations appear in documentation published by the European Union Agency for Cybersecurity, which focuses on preserving evidence chains when content may relate to compliance audits. Organizations that follow both sets of guidance often maintain parallel recovery environments that run validation checks in parallel with production systems.
Validation and Testing Procedures
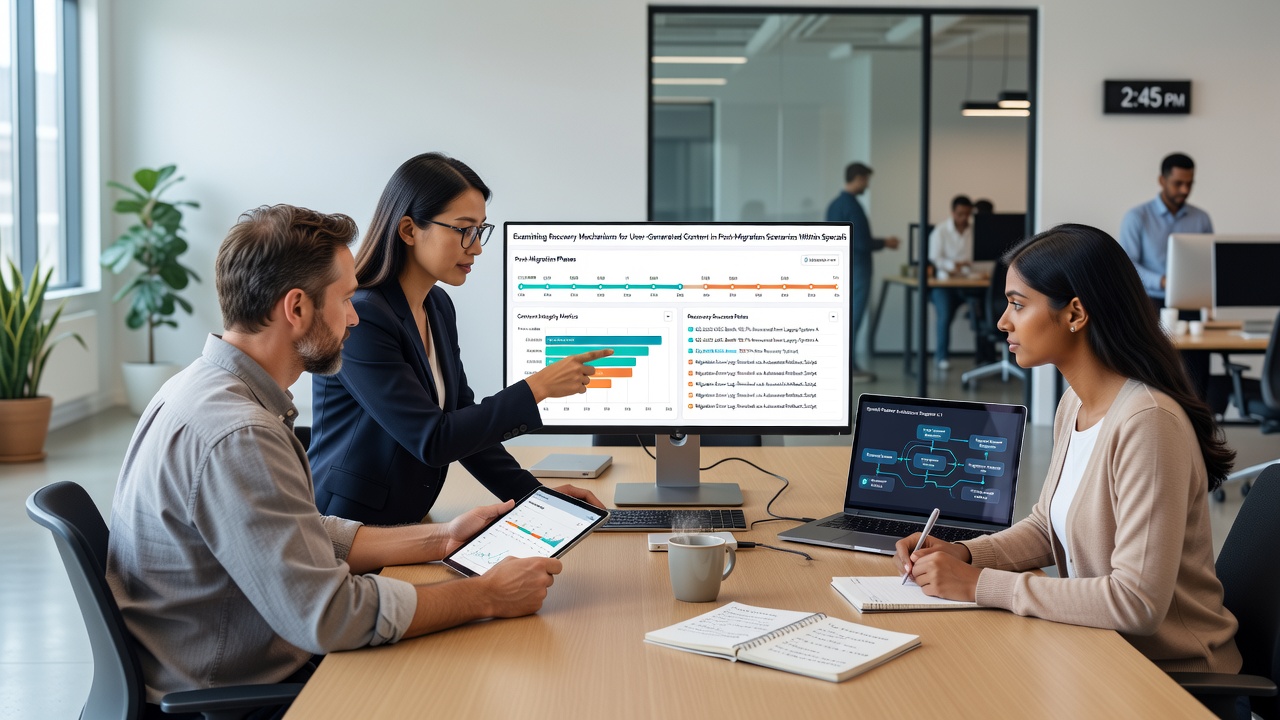
Teams perform staged restores into isolated sandboxes before allowing user access, and they compare record counts, file integrity hashes, and permission assignments against pre-migration baselines. Automated test suites now include synthetic user content that mimics real-world edge cases such as nested comments, large binary attachments, and cross-referenced documents. Figures reveal that these synthetic tests catch approximately 30 percent more discrepancies than manual spot checks alone.
Continuous monitoring after the initial recovery phase catches delayed issues that surface only when users interact with restored items. Log aggregation platforms track access patterns and flag sudden spikes in 404 errors or permission denials that point to incomplete content reconstruction.
Conclusion
Recovery mechanisms for user-generated content continue to evolve as specialized applications migrate between infrastructures. The combination of versioned storage, targeted validation scripts, and adherence to emerging regional standards provides measurable improvements in completeness and speed. Data from ongoing research projects suggests that further gains will arrive when September 2026 interoperability updates take effect across vendor ecosystems. Organizations that invest in layered recovery processes now position themselves to handle future migrations with fewer gaps in user content.